An Engineering Next-Generation Voice Agent Architecture
Explore how production-ready voice AI agents achieve natural conversations through low latency, real-time orchestration, robust state management.
Building a production-ready voice agent requires moving far beyond basic text-based LLM chains or simple API calls. In modern real-time applications, the challenge shifts from prompt quality to system architecture, latency optimisation, full-duplex orchestration, and robust state management.
When scaling voice systems to handle production traffic, teams encounter distinct distributed computing bottlenecks: context bloat, race conditions during tool execution, audio stream interruptions, and latency compounding.
The End-to-End Voice Pipeline
A modern production voice agent relies on an integrated, low-latency streaming pipeline that bridges speech processing with a stateful intelligence harness.
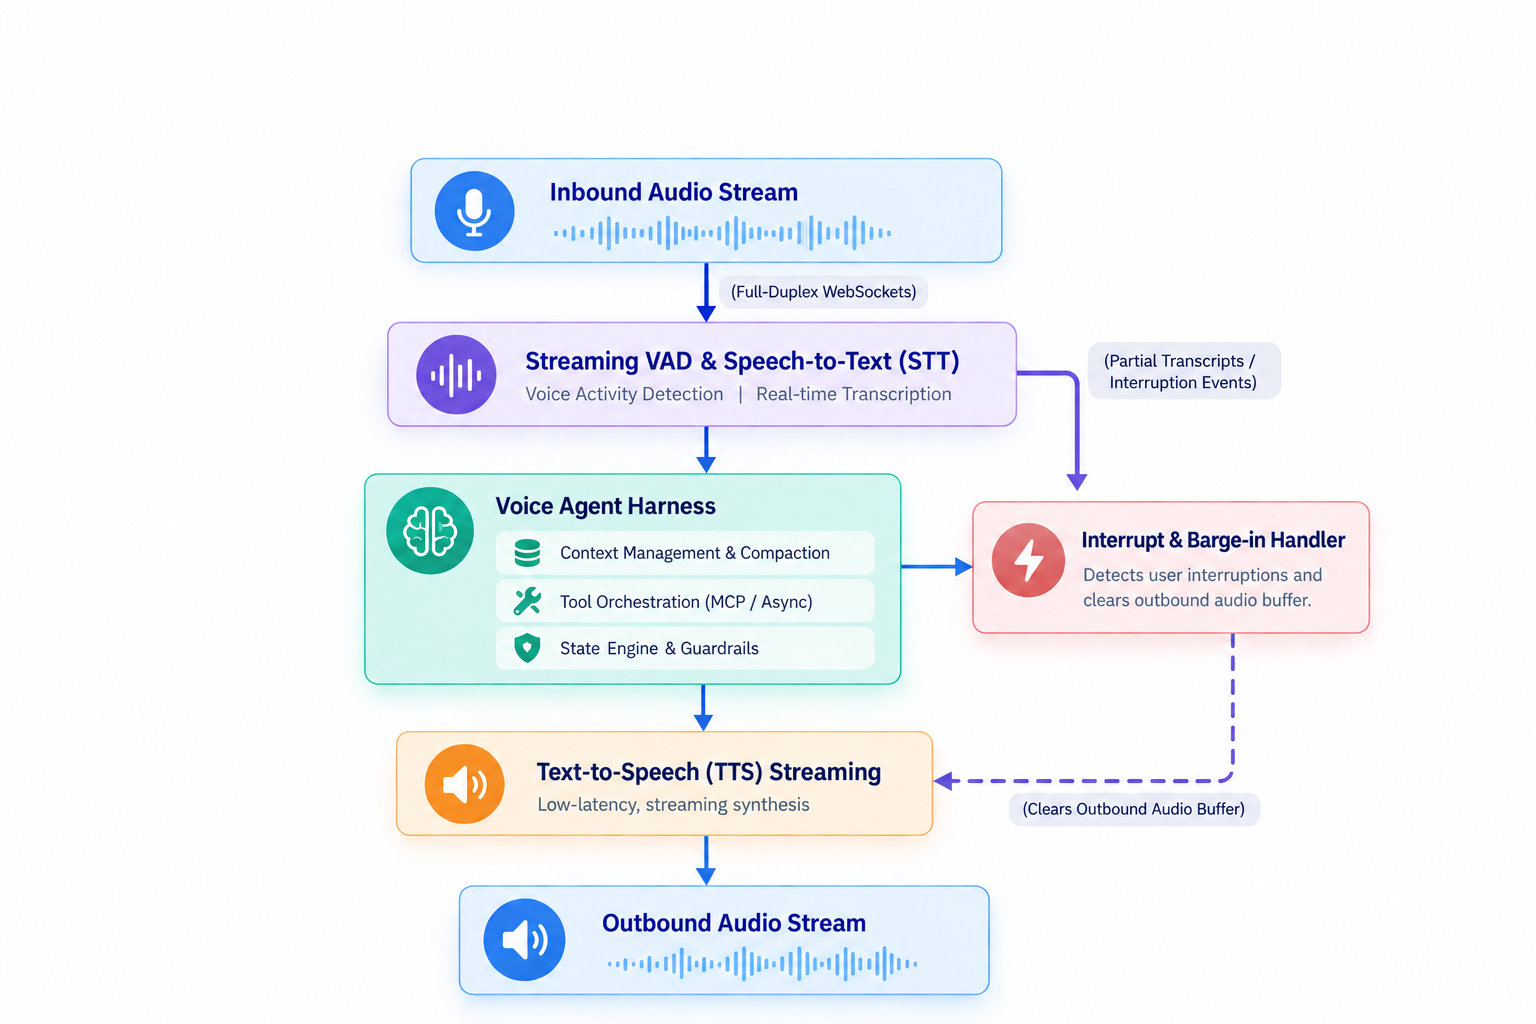
- Inbound Transport & VAD: Audio chunks stream continuously over bidirectional WebSockets. Voice Activity Detection (VAD) monitors silences and user speech starts, triggering immediate "barge-in" events when the user speaks over the agent.
- Speech-to-Text (STT): Streaming audio is converted into text tokens in real time, yielding speculative and finalised transcripts.
- Voice Agent Harness: The core software infrastructure wrapping the model. It manages prompt assembly, tool execution, context compaction, and persistent memory updates.
- Streaming Text-to-Speech (TTS): Response tokens generated by the model are immediately piped into a streaming TTS synthesiser, transmitting synthesised audio packets back to the client with sub-second latency.
Core Pillars of Production Voice Architecture
1. Ultra-Low Latency & Duplex Transport
To maintain natural conversation flow, human-to-human latency targets (~300ms–600ms) must be preserved.
- Transport Protocol: WebSockets or WebRTC are used over standard HTTP to maintain full-duplex communication, allowing simultaneous audio streaming and control signalling.
- Speculative Token Streaming: The agent harness streams generated text directly to the TTS model before the complete sentence is finalised, shaving hundreds of milliseconds off response times.
2. Voice Harness Engineering & Context Management
In long voice sessions, context windows quickly fill with conversation history, audio metadata, and tool output schemas. This causes "context rot", degrading model instruction-following and introducing latency spikes.
- Observation Masking: Hides verbose raw tool outputs while maintaining execution visibility in context.
- Compaction & Note-Taking: Periodically condenses historical conversation turns into key facts, maintaining strict token budgets to keep prefill latency minimal.
3. Event-Driven & Asynchronous Execution
Voice loops cannot freeze while waiting for slow database writes or third-party APIs.
- Decoupled Architecture: The voice conversation agent publishes events (e.g., ReservationRequested) and immediately acknowledges the user.
- Worker Execution: Background agents process heavy integrations asynchronously without stalling the primary conversational audio loop.
4. Deterministic Guardrails & Idempotency
Because audio interactions are fluid and prone to misunderstandings, execution safety is critical.
- Idempotency Keys: Network retries or repeated user confirmations do not execute duplicate backend operations (e.g., double payments or repeated bookings).
- Tripwires & Permission Hooks: Hardware-level rules and strict schema validation enforce business logic before tools can mutate external databases.
Architecture Pattern Comparison
Choosing the right pipeline structure depends on your target latency, budget, task complexity, and level of control required.
1. Cascaded Pipeline (STT → LLM → TTS)
A cascaded pipeline processes the conversation sequentially through three separate modules:
Speech-to-Text (STT) → Large Language Model (LLM) → Text-to-Speech (TTS)
- Latency: Moderate — approximately 600 ms to 1.2 seconds
- Control & Guardrails: High — each stage can be explicitly inspected and controlled
- Best suited for: Enterprise workflows, transactional voice agents, and multi-tool tasks where reliability and control are important
2. Real-Time Speech-to-Speech (S2S)
A real-time S2S architecture uses a single multimodal audio model that accepts raw audio input and streams raw audio output directly.
Audio Input → Multimodal Audio Model → Audio Output
- Latency: Ultra-low — approximately 250 ms to 400 ms
- Control & Guardrails: Lower — it can be harder to intercept or inspect the model's response during generation
- Best suited for: High-speed conversational agents, language practice, and low-complexity support scenarios where natural, fast interaction is the priority
Key Production Safeguards
- Barge-in & Interrupt Handling: When a user interrupts an active agent response, the client signals an immediate cancellation frame. The harness flushes the current TTS audio queue and updates the state graph with a dynamic interrupt.
- Graceful Fallbacks: If a specialised subagent or external API times out, the main voice loop delivers a natural conversational holding phrase rather than hanging silently.
- Graph-State Checkpointing: Every conversational state transition is persisted externally to allow fast recovery from network drops without dropping session context.
Voice AI Agent Engineering and Deployment
At Tweeny, we build and scale voice AI agents that hold a real conversation and survive contact with production. That means designing for the messy parts first: callers who interrupt mid-sentence, accents and background noise the demo never covered, and silences that need to be read rather than filled. Every conversion step in a cascaded pipeline costs you milliseconds and a little meaning, so we budget latency end to end and pick the architecture that fits the use case rather than the one that benchmarks well. The result is an agent that responds fast enough to feel like a conversation and recovers gracefully when a call goes sideways.
The Future of Voice
Building a high-performing voice agent requires a delicate balance of architectural rigour, low-latency optimisation, and state management. While selecting between Cascaded and S2S pipelines establishes the core performance and control profile, overall success depends on an integrated, event-driven infrastructure. Ultimately, creating seamless, natural human-agent interactions relies as much on robust system foundations as it does on the underlying generative models.
Frequently Asked Questions (FAQ)
Q1: What is the main difference between a cascaded pipeline and a native speech-to-speech (S2S) model?
- Cascaded Pipeline: Processes audio sequentially using three distinct models (STT → LLM → TTS). It is modular, highly observable, and allows using custom brand voices but suffers from higher latency compounding (600ms – 1.2s).
- Real-Time Speech-to-Speech (S2S): Uses a single native multimodal model that maps raw audio directly into latent acoustic tokens and back to raw audio. This achieves ultra-low latency (250ms – 400ms) and naturally understands emotional tone or paralinguistic cues (like laughter or hesitation), but lacks intermediate text logs and is more costly to run.
Q2: How does "barge-in" or user interruption work under the hood?
- When a user speaks over the agent, Voice Activity Detection (VAD) triggers an immediate interruption frame.
- The orchestrator instantly flushes the outbound Text-to-Speech (TTS) playback buffer, halts active LLM token generation, and records the exact point where the user interrupted the agent to update the state graph dynamically.
Q3: What is "context rot" in voice sessions, and how do you prevent it?
- In long conversations, the model’s context window quickly fills with raw transcripts, tool schemas, and audio metadata. This degrades instruction-following and spikes latency.
- Production systems prevent this through Observation Masking (hiding raw, verbose tool outputs) and Compaction (summarising historical dialogue turns into key facts periodically) to stay within tight token budgets.
Q4: Why does a production voice agent require an event-driven, decoupled architecture?
- Real-time voice loops cannot pause or hang while waiting for slow external APIs or database writes.
- A decoupled architecture allows the voice loop to publish background events (e.g., requesting a transaction) and immediately deliver a natural holding or confirmation phrase, allowing background workers to execute heavy operations asynchronously.
Q5: What is the optimal latency threshold for human-like conversational voice agents?
To maintain a natural, empathetic flow, the end-to-end response delay should target 300ms to 600ms (the typical human response gap). Delays extending past 1 second typically break the illusion of real-time interaction and lead to accidental overlaps or disengagement.
Explore more blogs

Building intelligent products, modern web platforms, and custom digital experiences.